The Most Common Technical SEO Trap
One of the most persistent and damaging mistakes in search engine optimization is confusing crawl prevention with index removal. Webmasters often discover low-quality, duplicate, or staging pages appearing in Google Search, add a Disallow rule to robots.txt, and expect the pages to disappear from search results.
Instead, the pages remain indexed indefinitely. Understanding the technical mechanics of robots.txt vs noindex is essential for every site owner and developer.
Robots.txt Governs Crawling, Not Indexing
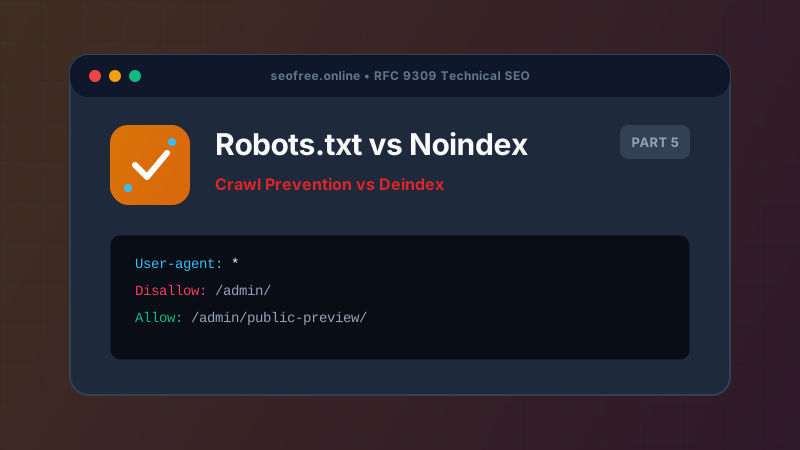
A robots.txt file operates at the network request level. When a search crawler encounters a Disallow: /path/ rule:
- The crawler is instructed not to send an HTTP GET request to that URL.
- The crawler never downloads the HTML, CSS, or JavaScript.
- The crawler never sees the
<meta name="robots" content="noindex">tag or any HTTP response headers.
Noindex Governs Indexing, But Requires Crawling
The noindex directive (implemented either as an HTML meta tag or an X-Robots-Tag HTTP response header) tells search engines: "You may read this page, but do not display it in search results."
For search engines to obey a noindex instruction, they must be allowed to crawl the page. If you block the page in robots.txt, Googlebot cannot fetch the document to read your noindex directive.
Direct Comparison Matrix
| Feature | Robots.txt Disallow | Meta Noindex / X-Robots-Tag |
|---|---|---|
| Primary Purpose | Manage server load & crawl budget | Prevent appearance in search results |
| Page Fetch Status | Crawlers never request the page | Crawlers download and parse the page |
| Indexation Outcome | Can still be indexed via external links | Guaranteed exclusion from index |
| Link Equity (PageRank) | Trapped; links on page cannot be followed | Links can be followed (if using noindex, follow) |
| Implementation Level | Single plain-text file at domain root | Per-URL HTML head or HTTP header |
How to Properly Deindex a Section of Your Site
If you have unwanted pages currently indexed that you wish to remove permanently:
- Ensure the pages are ALLOWED in robots.txt: Verify using our Bulk Robots.txt Tester that Googlebot is not blocked from crawling the URLs.
- Add the noindex directive: Inject
<meta name="robots" content="noindex, follow">into the HTML<head>of each target page, or return the HTTP headerX-Robots-Tag: noindex. - Wait for Googlebot to re-crawl: Once Googlebot fetches the page and registers the noindex instruction, it will drop the URL from search results.
- (Optional) Disallow in robots.txt later: Only after the pages have completely dropped from Google Search should you consider disallowing them to conserve crawl budget.
Frequently Asked Questions
Can I put "Noindex: /path" directly inside robots.txt?
No! Google officially dropped support for the non-standard noindex directive in robots.txt in September 2019. Including it will result in syntax warnings and will be completely ignored by Googlebot.
Why does Google index disallowed pages?
If another website links to your disallowed URL with descriptive anchor text, Google assumes the URL is relevant and lists it based on external link signals alone.
What should I use for search filter pages with thousands of parameter combinations?
If the pages have never been indexed, use robots.txt Disallow to prevent crawl budget waste. If they are already indexed, use noindex first or canonicalize them to the clean category URL.