Symptoms of a Googlebot Crawl Block
When Googlebot is blocked from accessing key sections of your website, the consequences are immediate and severe. Common warning signs include:
- Search Console reporting sudden increases in "Blocked by robots.txt" under the Page Indexing report.
- New content failing to be inspected or rendered in the URL Inspection Tool.
- Organic impressions dropping precipitously following a deployment or CMS update.
- Pages appearing in Google Search with a generic snippet stating "No information is available for this page."
Understanding Googlebot’s User-Agent Grouping
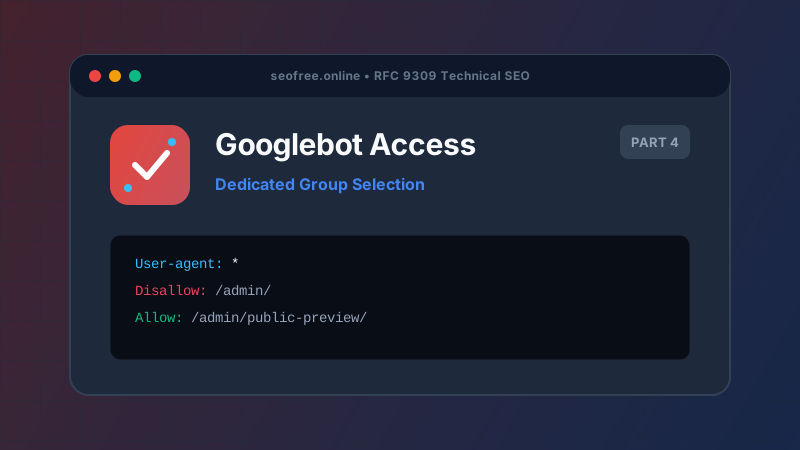
Google operates several specialized crawler tokens, with the primary web crawlers being Googlebot (standard web search) and Googlebot-Image (image search). When Googlebot accesses your robots.txt file, it checks for groups in this exact order:
- Dedicated Googlebot Group: A block beginning with
User-agent: Googlebot. If present, Googlebot obeys only these rules and completely ignores any rules in theUser-agent: *group. - Generic Wildcard Group: If no dedicated
User-agent: Googlebotblock exists, Googlebot follows the directives inUser-agent: *.
# Scenario A: Dedicated Group Overrides Wildcard
User-agent: *
Disallow: /

User-agent: Googlebot
Disallow: /admin/
Allow: /
In Scenario A above, generic bots are blocked from the entire site, but Googlebot is explicitly allowed to crawl everything except /admin/.
Step-by-Step Googlebot Verification Method
Step 1: Check the Live Robots.txt HTTP Header
Confirm that your robots.txt file itself is publicly accessible and returning an HTTP 200 status code. If your server returns an HTTP 500 error or requires HTTP Basic Authentication, Googlebot will treat the failure as a temporary site-wide crawl block.
Step 2: Run a Bulk Check with Crawler Emulation
Use our Bulk Robots.txt Tester. Select Googlebot from the crawler dropdown menu. Input the paths of your high-priority landing pages, category pages, and XML sitemaps. The tester will evaluate rule inheritance and highlight the decisive directive for each URL.
Step 3: Audit Asset Directories (CSS & JavaScript)
Ensure your robots.txt does not block access to critical frontend assets:
# DANGEROUS: Blocks modern rendering
User-agent: Googlebot
Disallow: /wp-content/plugins/
Disallow: /assets/js/
Googlebot renders pages using a headless Chromium browser. If stylesheets and JavaScript files are disallowed, Googlebot cannot compute mobile responsiveness, hidden content, or layout stability, damaging your rankings.
Frequently Asked Questions
Can I block other crawlers while keeping Googlebot allowed?
Yes. Define a dedicated User-agent: Googlebot block with Disallow: (empty, allowing all) or specific path permissions, and set User-agent: * with Disallow: /.
Does blocking Googlebot remove existing pages from search results?
No! Blocking crawling prevents Google from seeing updates or noindex tags. To remove pages, keep them crawlable and add a noindex tag.
How quickly does Googlebot update its cached copy of robots.txt?
Google typically caches robots.txt files for up to 24 hours. You can submit an expedited re-crawl request through Google Search Console.